Reduce token spend by 90%
Automatically route to the right model based on the task, latency, quality and cost.
Models selected for quality
01
Send a prompt
Call the OpenAI-compatible API with sansa-auto. Your application code stays the same.02
Sansa matches the work
The router predicts the capabilities your prompt needs and scores the available models.03
The best-fit model responds
Sansa selects the strongest match, runs the request, and returns the response.

/ benchmarks
Routing that wins on benchmarks
Sansa routing beats all frontier models on MMLU-Pro accuracy by sending routing requests based on which model's capability profile is most likely to succeed.
Methodology
- Dataset: MMLU-Pro
- Protocol: Aggregated accuracy across routed completions
- Scoring: Exact match reported as accuracy (%)
- Results: Published sansa-auto run are on GitHub
- Run it: sansa-mmlu-pro
/ efficiency
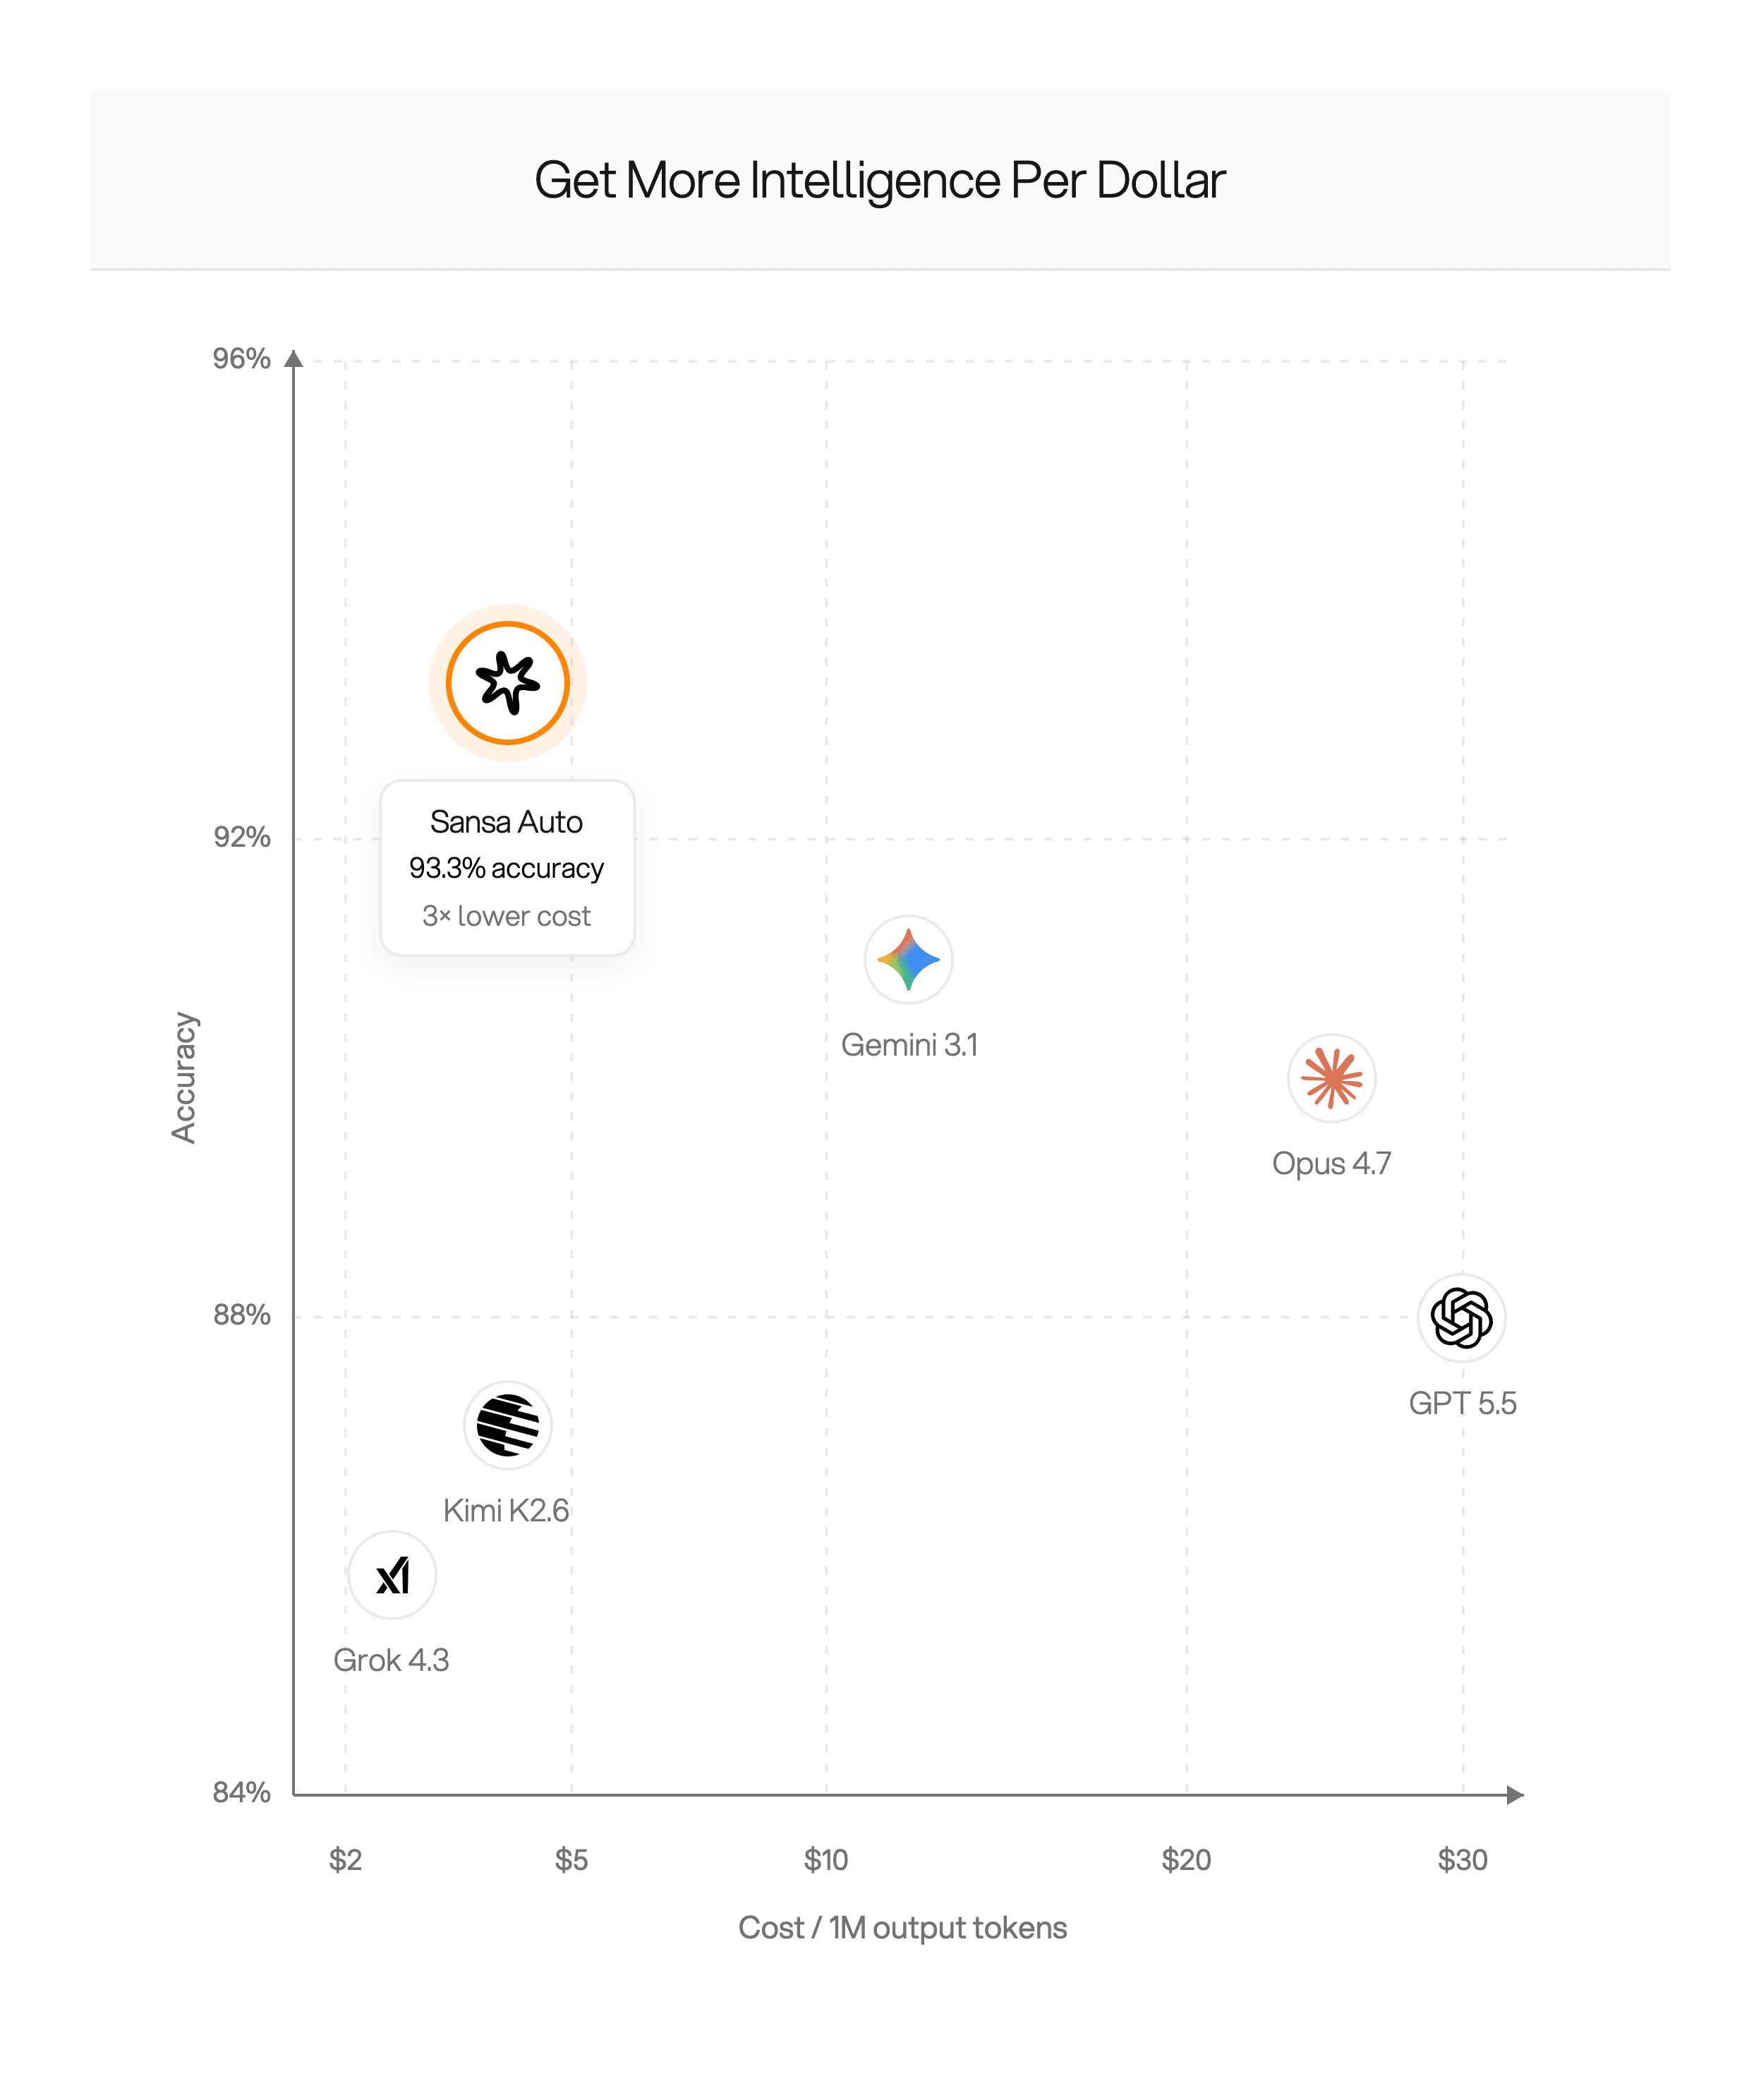
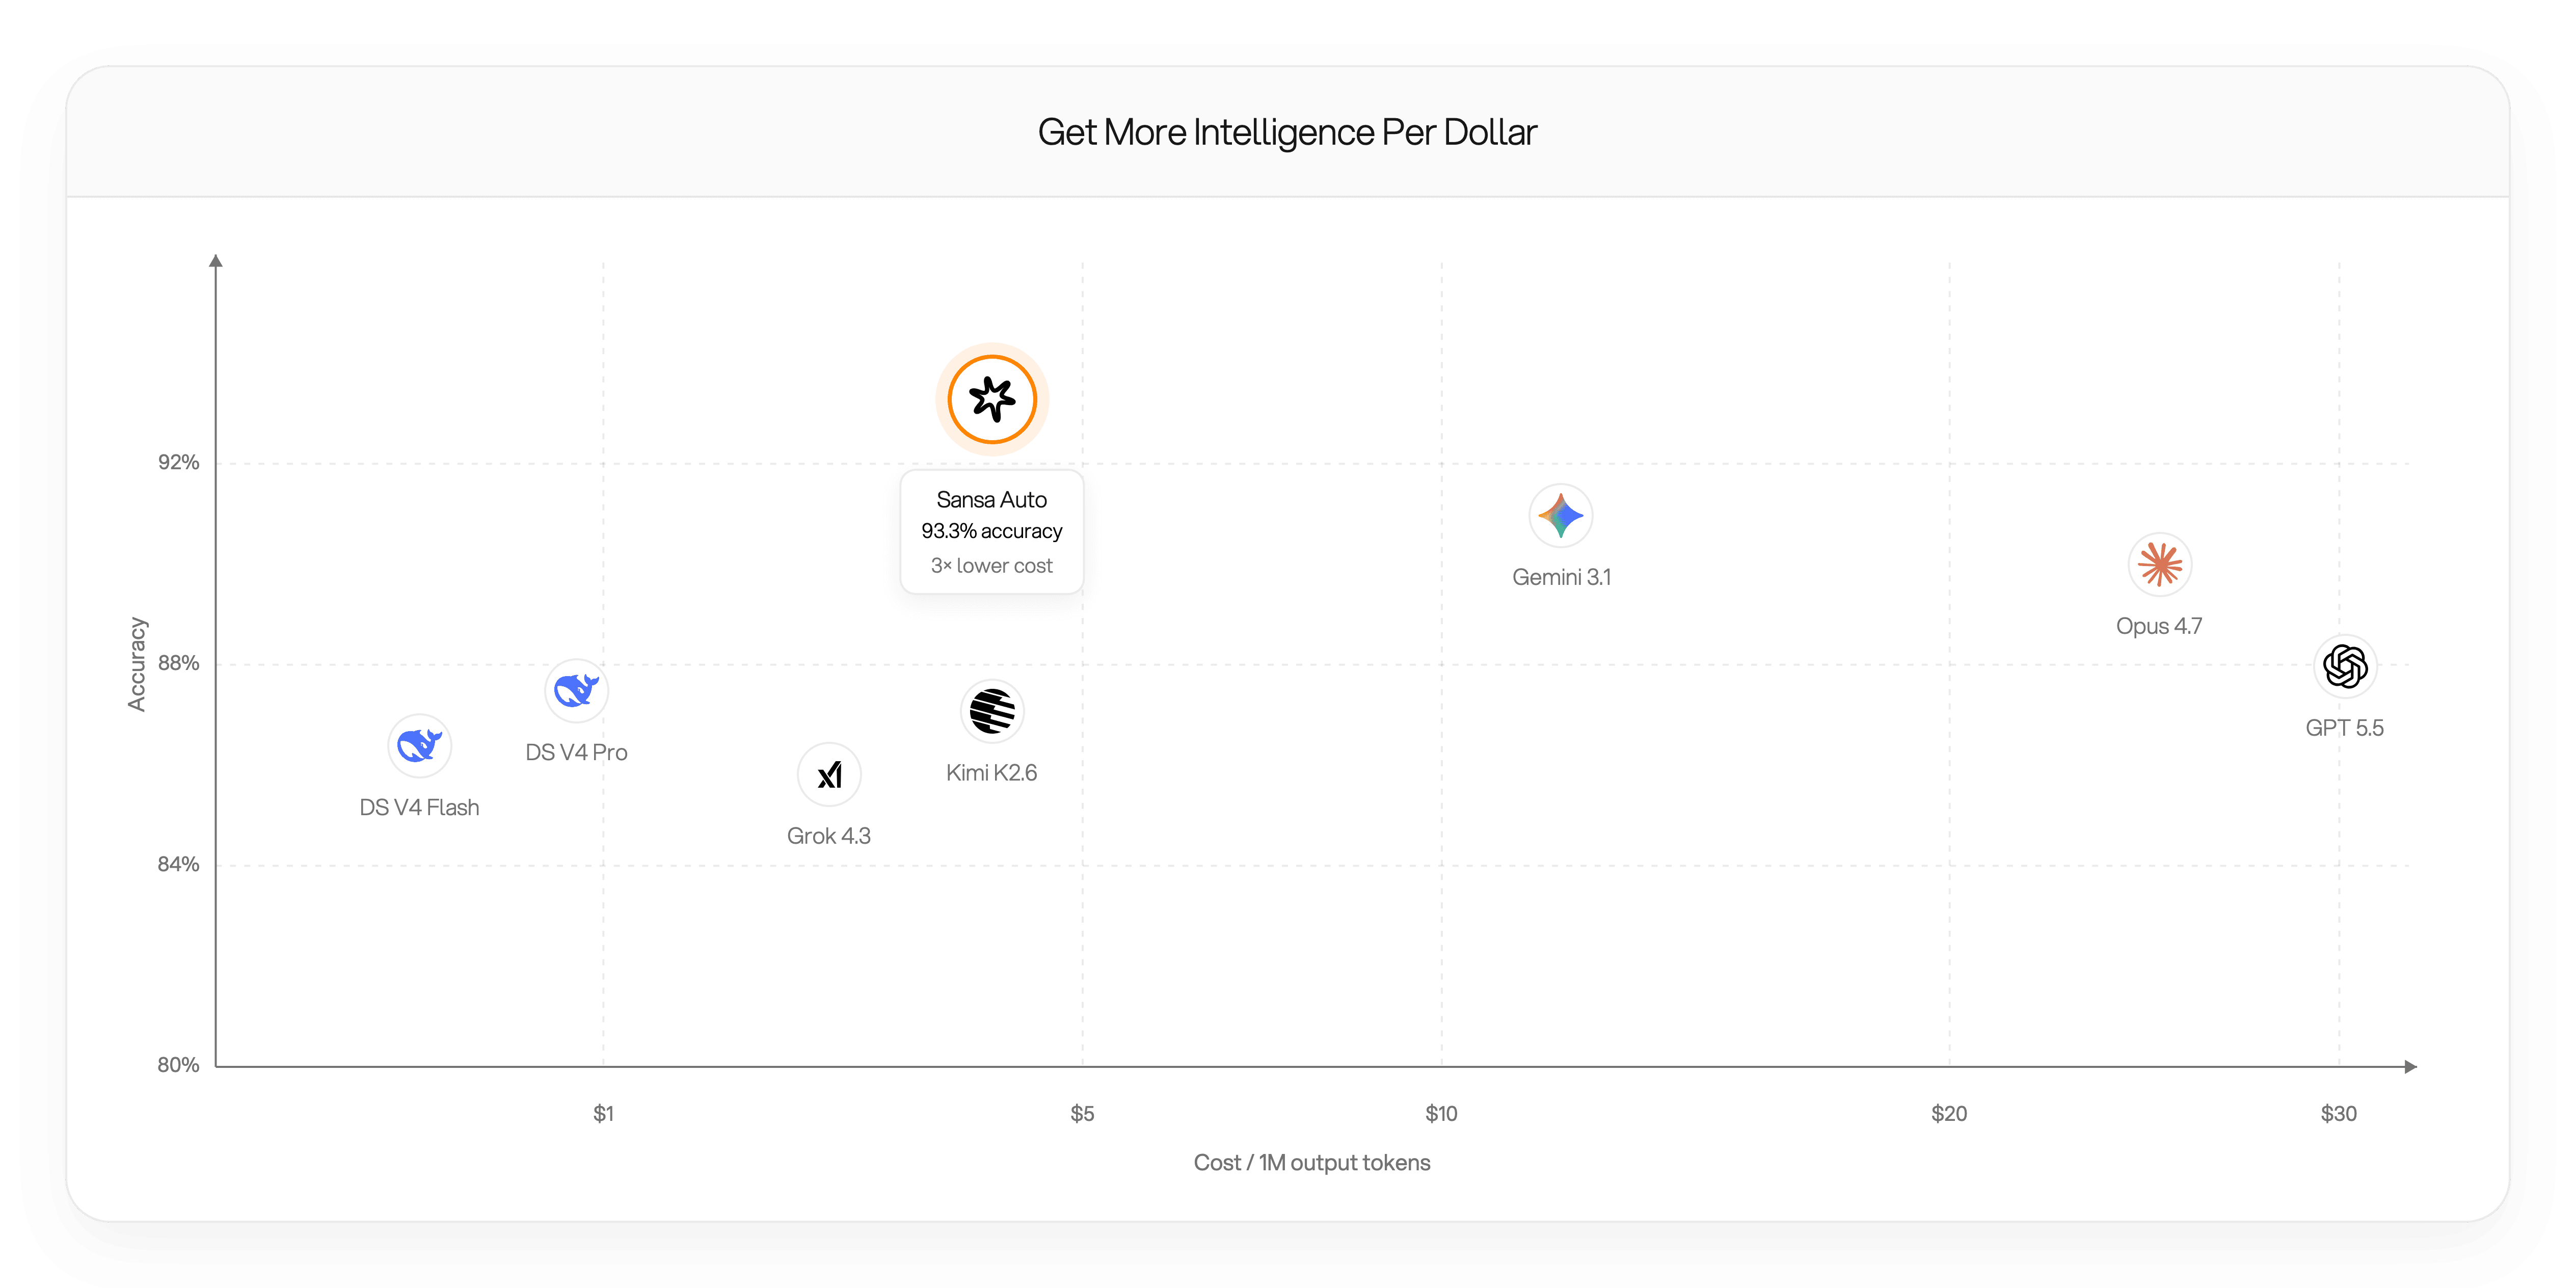
Get more intelligence per dollar
Sansa Auto compares frontier models on quality and output cost, then routes each request to the strongest fit so you avoid premium-model prices.
/ observability
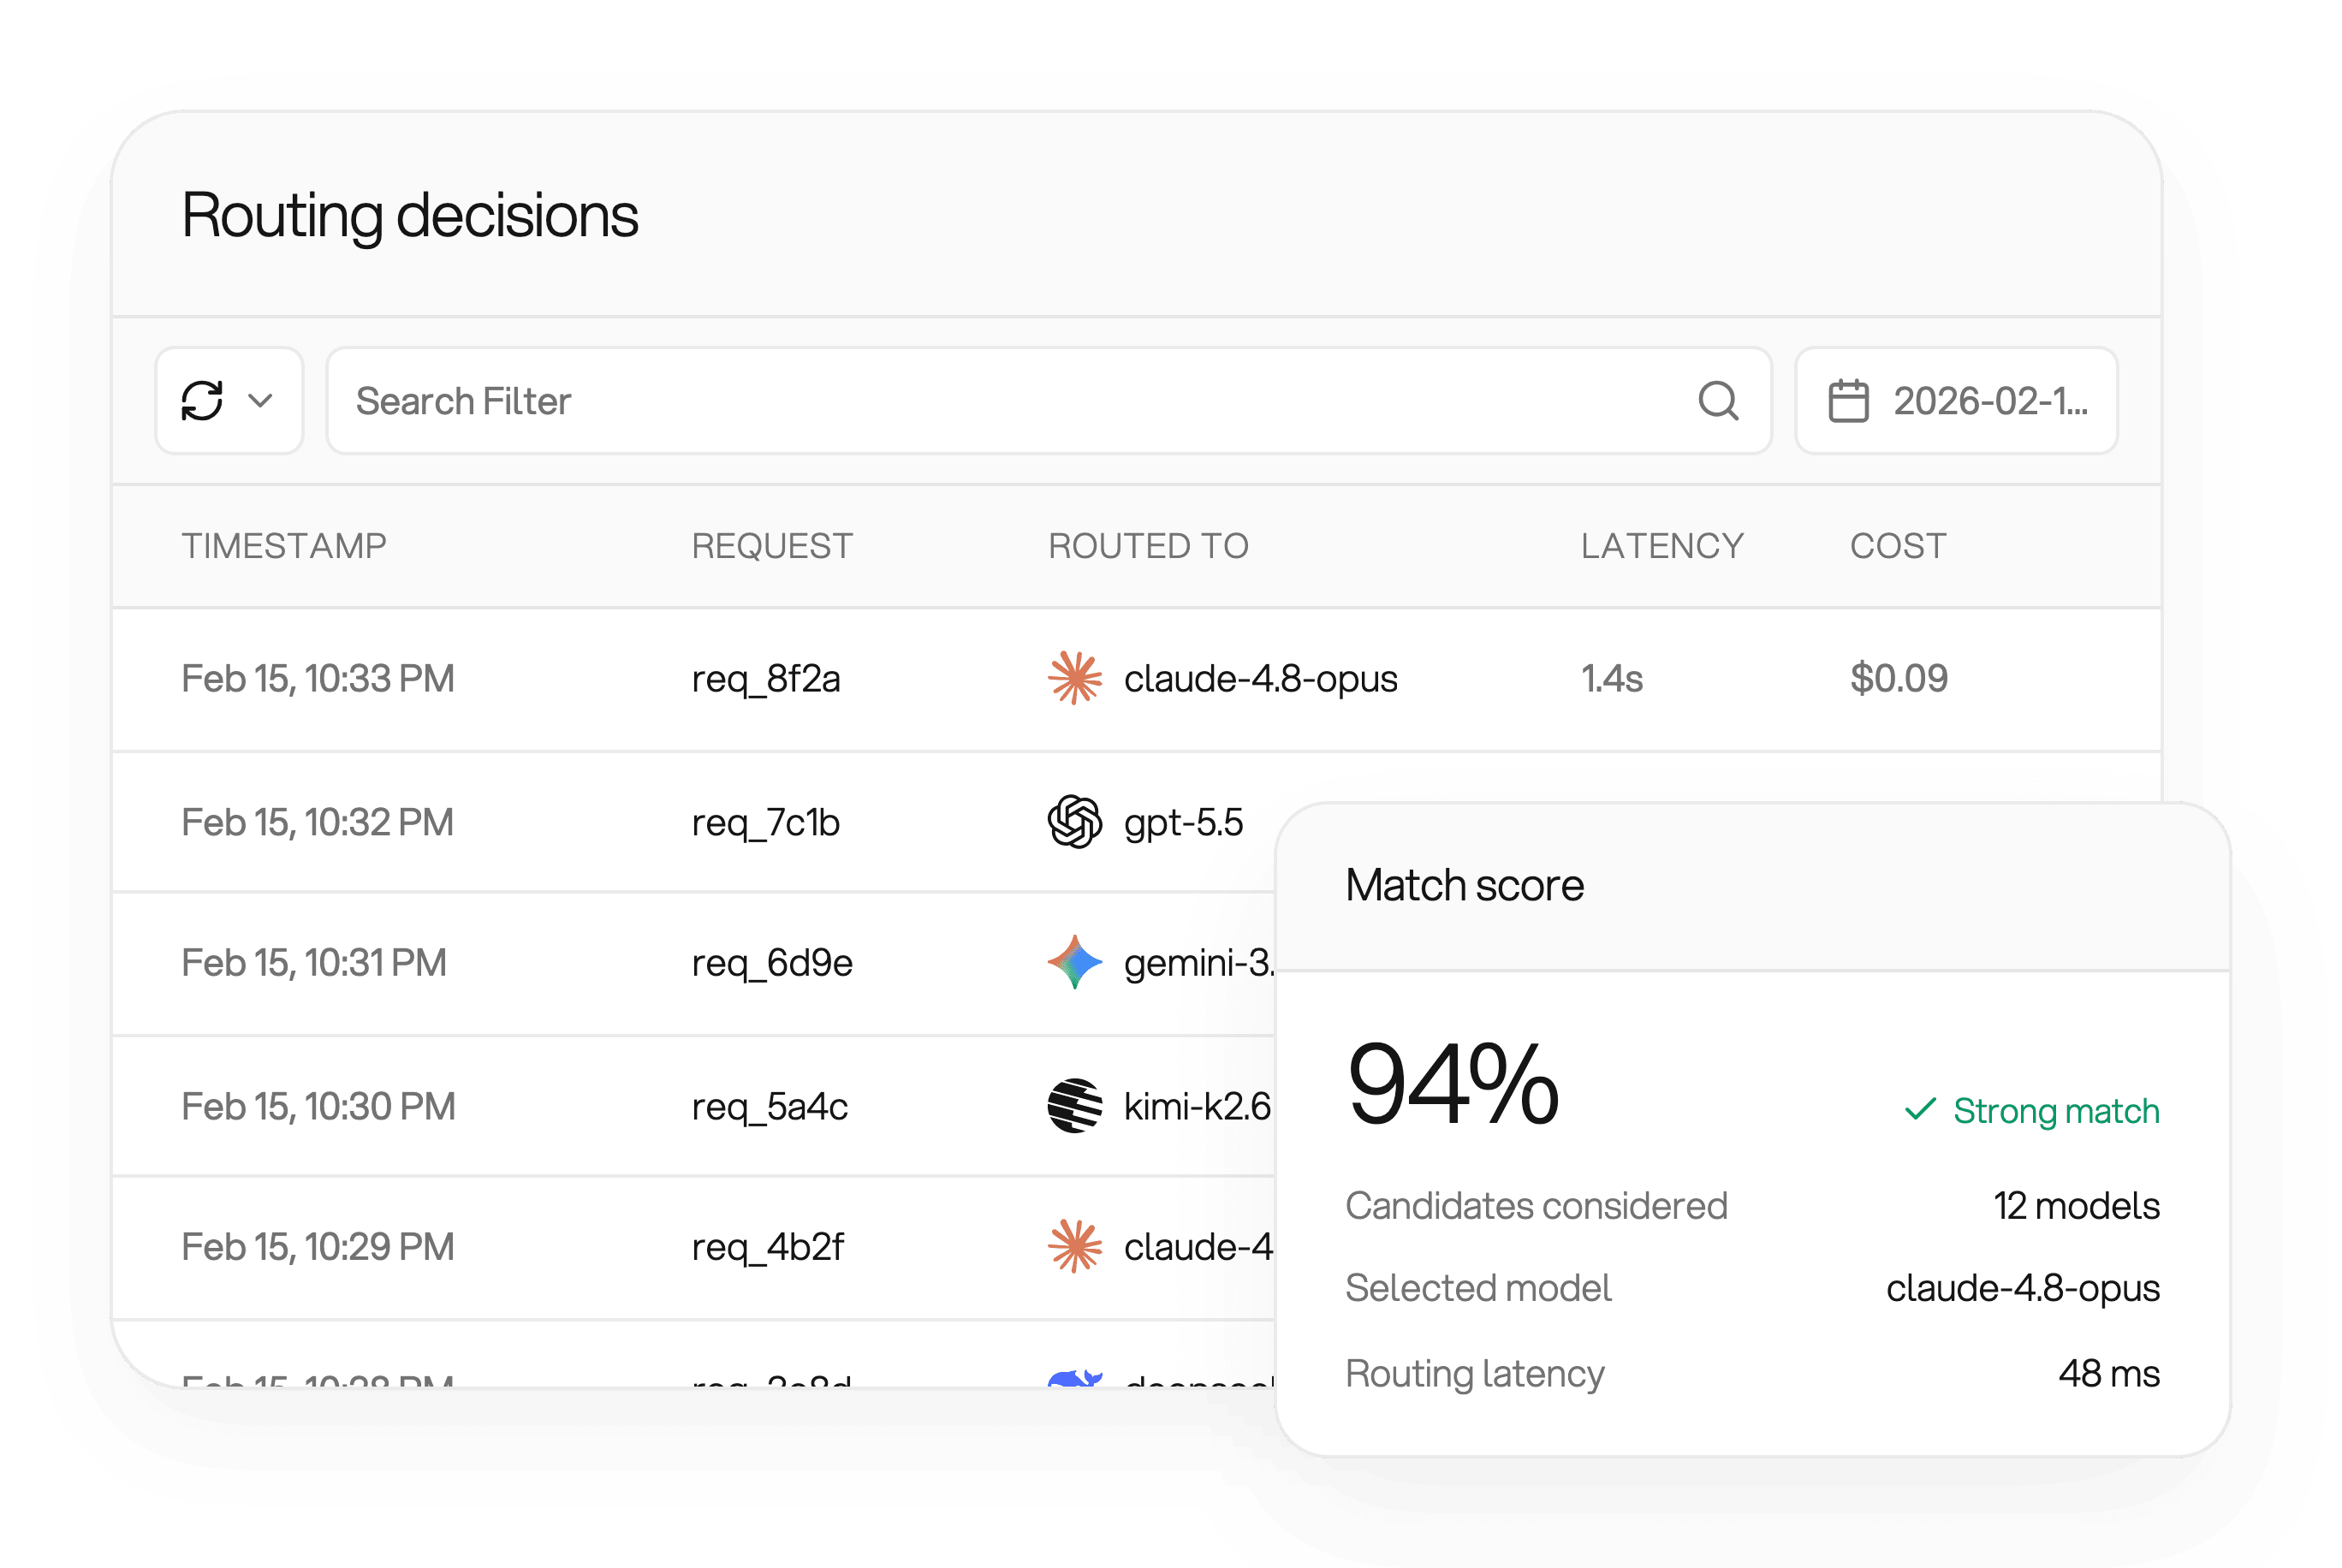
Know exactly what ran, and why
Every model match is logged, so you can debug issues and track performance over time.